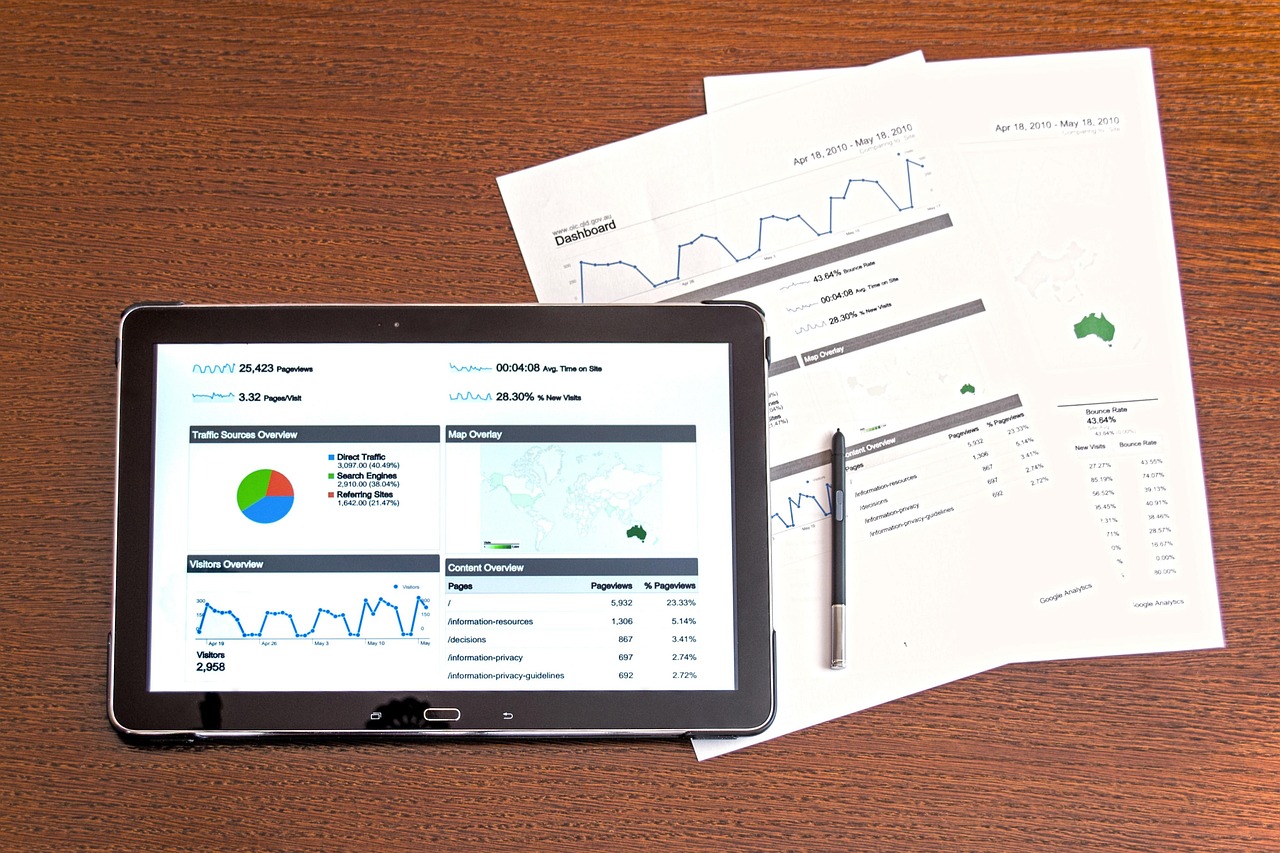
Many site owners want accurate traffic measurement without handing visitor data to third parties. Self‑hosting your analytics reduces external exposure, gives you control over retention and data exports, and makes it easier to adopt privacy‑preserving defaults.
Why self-hosted analytics reduce tracking risk
Third‑party analytics often load code and set cookies from domains you do not control. That arrangement creates opportunities for cross‑site profiling and for data to be shared or sold outside your organisation. Self‑hosting moves the collector to infrastructure you operate or pay for directly, narrowing who can access raw event data and allowing you to enforce stricter retention, access and deletion policies.
That does not make tracking harmless: a self‑hosted system can still collect identifiable data if configured that way. The privacy benefits come from choosing a privacy‑first platform and from operational choices such as avoiding persistent identifiers and minimising data retention.
Overview of lightweight platforms and trade‑offs
Choose a platform based on the feature set you need and the privacy guarantees you want. Lightweight analytics focus on page views, conversions and basic referrer data, while feature‑rich platforms provide funnels, session recordings and advanced segmentation but often require more storage and configuration.
Popular self‑hosted choices
- Plausible — Aims for minimalism and privacy: small script, simple dashboards and defaults that avoid personal data. Good for site owners who want straightforward metrics and low maintenance.
- Matomo — A long‑standing, feature‑rich platform that can be configured for privacy. It supports many integrations and custom reports but will need more resources and attention to harden for privacy by default.
- Other lightweight options — Several open projects trade off features for simplicity: they typically provide a tiny JS beacon and aggregate data only. These are useful when you want near‑zero impact on page load and limited data collection.
Trade‑offs to weigh:
- Accuracy vs privacy: Removing identifiers reduces the ability to deduplicate or track returning visitors, which affects metrics like unique users.
- Feature set vs maintenance: More features mean more components to update and secure.
- Resource requirements: Lightweight tools run comfortably on small VPS instances; heavier platforms may need a dedicated database and more disk.
Basic installation options: Docker, managed and serverless
There are three practical paths to deploy self‑hosted analytics. Each suits different skills, budgets and operational models.
Docker / VM (self‑managed)
Running via Docker or on a virtual machine is the most common choice for small teams that want control without complex orchestration.
- Provision a VPS with a stable OS and firewall rules.
- Run the analytics service and a database (if required) as containerised services, ideally managed with docker‑compose or a simple systemd unit.
- Place the tracker script on your site and point it to your collector domain (e.g. analytics.example.com).
# Minimal docker‑compose outline (replace with project docs)
services:
  db:
    image: mariadb:latest
    volumes: ["db-data:/var/lib/mysql"]
  analytics:
    image: your-analytics-image
    depends_on: [db]
volumes:
  db-data: {}
Always follow the project documentation for required environment variables, ports and persistence locations.
Managed (hosted by vendor)
If you prefer to avoid system administration, some projects offer paid hosted plans. Managed hosting removes the operational burden of OS and security updates but reintroduces a third party into the trust model — consider the vendor’s privacy policy and data location before using hosted plans.
Serverless / collector endpoint
Serverless collectors (function‑based endpoints) can accept beacon requests and forward them into an analytics store or queue. They minimise server maintenance and scale automatically, but costs can rise with high request volumes and you must still manage where raw events are stored.
Measuring without identifiers and respecting privacy
Privacy‑first measurement relies on collecting the minimum useful data. Consider these practical controls:
- No persistent identifiers: Avoid setting long‑lived cookies or inserting user IDs that survive across browsing sessions.
- IP handling: Truncate or anonymise IP addresses as soon as they arrive to reduce the risk of direct location or device fingerprinting.
- Client‑side minimisation: Use a small, non‑tracking script that sends only page path, referrer and an anonymised user agent or browser family rather than full user agent strings.
- Aggregation and sampling: Aggregate events frequently and sample high‑volume traffic to limit the granularity of stored records.
- Do not record inputs or pages with personal data: Ensure any form or query parameters that may contain names or emails are stripped client‑side before sending events.
Be aware of browser fingerprinting: even without cookies, a combination of headers and APIs can make users distinguishable. Reduce this risk by limiting the set of attributes you collect and by avoiding techniques that read device features. For broader mitigation techniques, see our guide on Understanding Browser Fingerprinting.
Operational concerns: updates, storage and backups
Running your own analytics means you are responsible for availability, security and data governance.
Updates and security
- Track upstream security advisories for the platform you run and apply updates promptly; containerised deployments simplify rollbacks and reproducible upgrades.
- Harden the collector endpoint: serve it over HTTPS, rate limit requests and protect admin interfaces behind VPN or strong authentication.
Storage, retention and backups
- Define a retention policy that matches your needs — shorter retention improves privacy and reduces storage costs.
- Back up analytics databases regularly and test restores. Keep backups encrypted at rest and restrict access to the backups themselves.
- Consider periodic export of aggregated metrics (CSV/Parquet) and archiving of raw events only when necessary for compliance or analysis.
Operational monitoring
- Monitor collector availability and queue/backlog sizes if you use asynchronous ingestion.
- Alert on sudden drops or spikes in traffic that may indicate instrumentation regressions or abuse.
Simple checklist to get started
- Choose a tool aligned with your priorities (minimal footprint vs advanced features).
- Decide deployment model: self‑hosted on Docker/VM, vendor‑hosted, or serverless collector.
- Configure privacy defaults: no persistent identifiers, IP anonymisation, short retention.
- Harden the endpoint: HTTPS, authentication for admin, and firewall rules.
- Instrument pages and validate data flows in a staging environment before going live.
- Set a schedule for updates, backups and log reviews.
If you are migrating from a third‑party provider, our privacy‑friendly alternatives article explains migration considerations and trade‑offs that matter when moving away from common trackers.
Closing — start small, measure responsibly
Self‑hosted analytics let you retain useful measurement capability while reducing the privacy risks introduced by third parties. Begin with a minimal deployment, adopt strict defaults (no persistent identifiers, short retention) and scale features only as operational discipline allows. That approach gives you reliable site metrics without rebuilding visitor profiles.